PYCON ID 2026 · SHORT TALK

Benchmarking
Offline LLM Agents
in Bioinformatics

connected an LLM as interface to a genomics database, then spent most of the project working out how to tell whether it was right.

Kayla Queenazima · Github: kaylaque · chatbgc.matinnu.org/
Stylised bacterium
WHAT THIS TALK IS

One experiment, and how I think about benchmarking an LLM system. Early results — I have more questions now than when I started.

Not a finished study, and not a set of best practices.

SPEAKER NOTES · 0:00 – 0:25

Say the honest version out loud: most of the work was measurement, not model choice. Set the expectation that this is open-ended.

Next: who I am.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org01 / 14
§0 · WHO'S TALKING · 0:25

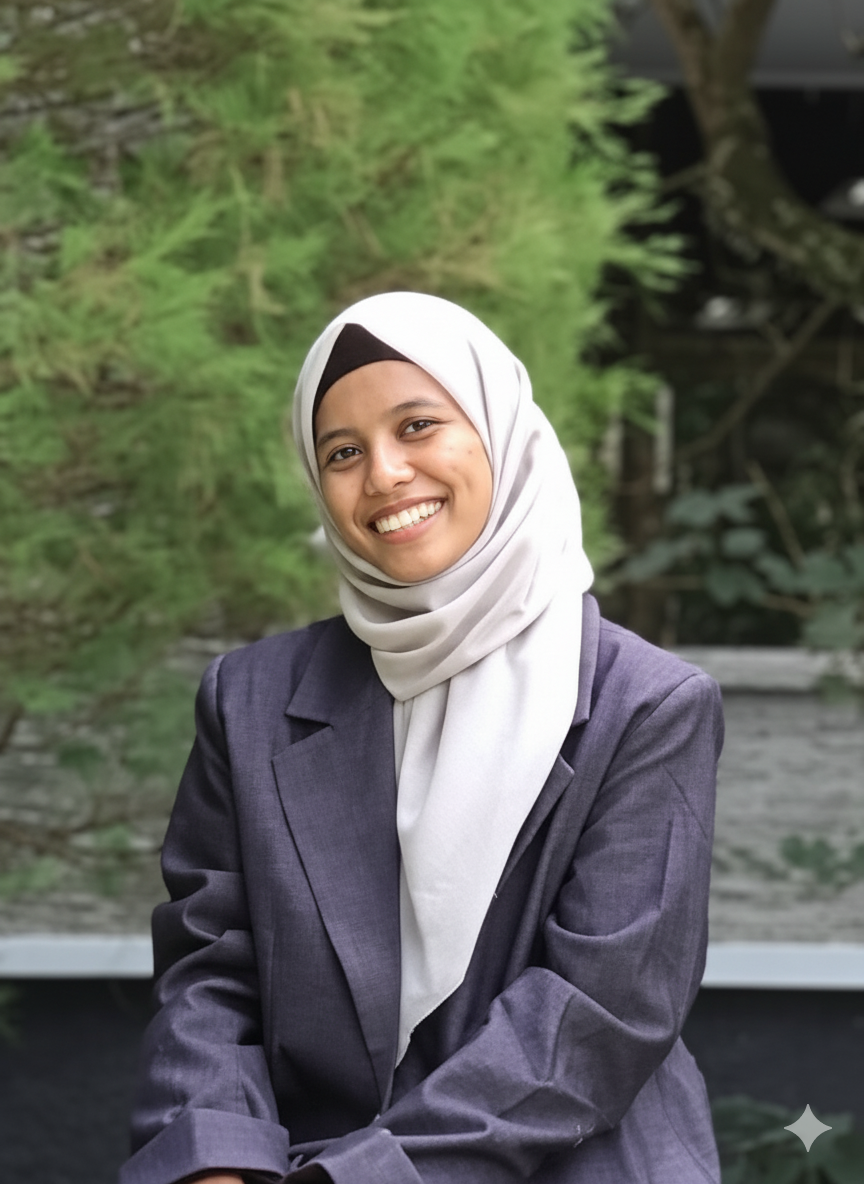
Hi, I'm Kayla!

◆What I do
AI Engineer at Hysn Technologies · Organizer, PyLadies Yogyakarta.
◆And part-time RA at the BEAMS Lab, Faculty of Biology, UGM
I work on chatBGC — connecting an LLM to a biosynthetic gene cluster database so people can query it in plain language.
◆You don't need biology for this talk
Kayla Queenazima
SPEAKER NOTES · 0:25 – 0:50

Twenty seconds. The third line is the one that matters — say it and move on.

Next: the actual problem.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org02 / 14
§1 · THE PROBLEM · 0:50

How do you ask a biology database a question without knowing 65 tables?

Biologist has a question "Do we have anything on X?" plain English, one sentence Someone writes the SQL knows the schema and the joins a few hours later… DuckDB · 65 tables every fact already in here answer comes back
WHY THE TRANSLATION IS THE EXPENSIVE PART

The model has never seen this schema

65 tables with names that don't self-explain. Nothing in pre-training tells it how they connect.

Valid joins need expert context

Which path between two tables is the right one is a domain judgement, not a syntax question.

Wrong-but-valid returns rows

No error. No warning. Just a plausible answer that a non-SQL user cannot check.

LLM hallucination
Invents a column or a table that does not exist. Loud — the query fails.
Domain hallucination
Uses real tables, valid SQL, and still answers a different biological question. Quiet — and much worse.
SPEAKER NOTES · 0:50 – 1:40

Corridor story first. Then the three cards quickly. Spend your time on the two hallucination types — the second one is the reason the rest of the talk exists.

Next: why is the database shaped like this?

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org03 / 14
§2 · THE DOMAIN · 1:40

Why does biology turn into a messy SQL problem?

Bacterium Genome / DNA Gene cluster Secondary metabolites antibiotics · antifungals · pigments antiSMASH finds the clusters SQL database
WHAT A RESEARCHER GETS OUT OF IT
how many clusters, per genome and genus how novel each one is vs known compounds which enzyme domains and substrates cluster architecture taxonomy links
Why the schema gets messy
It starts with one need — store the clusters we found. Then product types, then domains, then substrates, then comparisons against known compounds. Each new need adds tables and junctions. Nobody designed the mess; it accumulated.
SO A SINGLE QUESTION TOUCHES SEVERAL TABLES
regionsregion_idcontig_id
modulesregion_idtrans_at
rel_regions_typesregion_idbgc_type_id
bgc_typesbgc_type_idterm

regions and bgc_types have no direct key — you go through the junction table or you get nothing.

SPEAKER NOTES · 1:40 – 2:35

Walk the loop once: bacterium, genome, cluster, compounds, antiSMASH, database. Then the chips — that is what people actually want to ask about. The "nobody designed the mess" line usually lands.

Next: so what did I build?

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org04 / 14
§3 · THE SYSTEM · 2:35

Solution: an LLM interface for everyone

especially biologists without coding knowledge
Question plain English Retrieve schema + past examples LLM writes SQL plan, then generate DuckDB runs it, returns rows LLM explains rows → a sentence Answer
FOUR DESIGN CHOICES, AND WHAT FORCED THEM

Data can't leave

Unpublished genomes, so everything runs locally on one GPU.

Low concurrency

A lab, not a service. Optimise one request, not throughput.

Repeatable, with memory

Past question → SQL pairs are stored and reused, so the system gets better from use.

A model router

Different steps can use different models, to spend the local GPU where it counts.

So why benchmark any of this?
Every one of those choices is a guess until it is measured. Benchmarking is how I find out which parts of the design are earning their complexity — and which parts I built for no reason.
SPEAKER NOTES · 2:35 – 3:25

Trace one question across the pipeline. Then the four cards fast. The callout is the hinge of the whole talk: benchmarking exists to stop me over-engineering.

Next: what does correct even mean here?

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org05 / 14
§4 · BUILDING THE EVALUATION · 3:25

Building the evaluation: what does "correct" even mean?

Question Is the SQL valid? deterministic Are the rows right? deterministic Was the method valid? deterministic Does the answer fit? deterministic + LLM judge an agent can fail at any of these, and only the last one is visible to the user
WHY THIS IS HARDER FOR AN AGENT
◆Many decision points, not one
The agent chooses what to retrieve, what to plan, what SQL to write, whether to retry, and how to phrase the result.
◆No single method covers them all
Most checks can be deterministic. Only the final wording needs a judge — and that is the least reproducible check, so I keep it optional and off by default.
WHAT I ACTUALLY MEASURE
Execution accuracyrows match a known-good query1 / 0
Negative casescorrectly says "nothing found"1 / 0
Domain rulesschema prefix, junction path, read-only0–1
Answer faithfulnesssentence matches the rows fetched0–1
No-errorkept off the accuracy axis1 / 0

Seven layers in total — the full set is in the appendix.

SPEAKER NOTES · 3:25 – 4:20

This is the conceptual centre. Walk the four checkpoints, then say the red line out loud. Deterministic wherever possible; the judge only for phrasing.

Next: what I varied.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org06 / 14
§5 · THE EXPERIMENT DESIGN · 4:20

I varied the agent, the model, and the question — not just the model.

9
AGENT ARCHITECTURES
×
3
MODELS
×
41
QUESTIONS
=
1,107
RUNS

Agent architecture

From one-shot SQL up to a second model critiquing the first.

What I want to know
Does more autonomy actually help, or just cost more?

Model type and size

A 27B generalist, a 7B SQL specialist, and a hosted free model.

What I want to know
Do I need a big model, or the right one?

Question type

Simple lookups, joins, aggregations — plus 14 where the answer is "nothing found".

What I want to know
Which shapes of question can it handle at all?
The goal is diagnosis, not a leaderboard
A single ranking tells me who won. Tagging every run by agent, model and question shape gives me a first entry point for why something failed.

One replicate per combination — the known weak spot. One 48 GB GPU.

SPEAKER NOTES · 4:20 – 5:10

The multiplication is the visual. Then one line per dimension — say the "what I want to know" line, not the description. Be honest about the single replicate.

Next: early results.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org07 / 14
§6 · EARLY RESULTS · 5:10

Early results: which model wins?

0.80 0.75 0.70 0.65 0.60 0 s 3 s 6 s 9 s 12 s EXECUTION ACCURACY MEDIAN LATENCY PER QUESTION → Qwen 27B 0.767 · 5.5 s · local Laguna-XS provisional 0.666 · 2.5 s · local DeepSeek 0.645 · 11.9 s · hosted Router provisional 0.637 · 1.1 s · 2 local models XiYanSQL 7B 0.612 · 2.0 s · local

All scored runs, single replicate. Dashed = provisional — those two sweeps lost runs to a server fault and a wiring error, so their position here is a floor, not a score. Matched like-for-like they sit at 0.673 and 0.642 against Qwen's 0.769.

01Hosted vs local
The hosted free model is the slowest thing on this chart by more than 2×, and Qwen beats it by 12 points from one GPU under my desk. Local was not the compromise.
02General vs specialised
The 7B SQL specialist answers in 2.0 s against Qwen's 5.5 — and scores 15 points lower. The speed came out of accuracy, not for free.
03Single model vs several
I ran a two-model router this week — small model interprets, big model writes SQL. It lost 13 points of execution accuracy against Qwen alone. More on that in a moment.
Models as run
Qwen3.6-27B-FP8, official safetensors · XiYanSQL 7B, community build quantised to AWQ INT4 · DeepSeek Flash v4, free tier via the opencode endpoint · poolside/Laguna-XS-2.1-INT4, INT4 · plus a Qwen + XiYanSQL per-stage router. Both dashed on the chart, both explained on the closing slide.
SPEAKER NOTES · 5:10 – 5:55

Let the chart sit before talking. Three insight lines, then the model provenance — the quantisation matters for anyone trying to reproduce this. If asked why the two dashed points are low: those are floors, not scores — one sweep lost 200 runs to a server fault, the other ran with its model tiers wired backwards. Matched like-for-like they are 0.673 and 0.642 against Qwen's 0.769. End on the question and pause.

Next: same question, per architecture.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org08 / 14
§6 · EARLY RESULTS · 5:55

Early results: which model wins? (2)

DEEPSEEKQWEN 27BXIYAN 7BLAGUNAsmall nROUTER2 models
t0 one shot.793.732.159.850.800
t1 think + retry.768.780overflow.833.861
t2 retrieval.512.829.749.800.557
t3 picks own tool.692.647.334.500.502
t4 plan-execute.561.748.598.667.681
t5 critic loop.700.854.788.696.671
h1 retrieval + loop.718.664.744.567.550
h2 draft + revise.554.793.761.613.513
baseline plain pipeline.512.841.749.727.603

Execution accuracy, pooled. n = 30–41 per cell, except Laguna at 9–30 — its sweep lost 200 runs and the survivors skew easy, so read that column as provisional.

Best trade-off among the models that finished
t5 — the critic loop is top-band for both local single models (.854 and .788). That is the row I would build on.
No architecture wins everywhere
t0 runs from .159 to .850 across this row — the same code, a 0.69 swing. Small and weak models do better with less room to reason; the strong one does better with more.
And the ranking flips when you route
Qwen's best three — t5, baseline, t2 — are three of the router's worst four. Splitting work across two models reordered the architectures. Any leaderboard has to name the model and the route.
SPEAKER NOTES · 5:55 – 6:40

Do not read the grid. Point at the t0 row and sweep left to right — .159 to .850 on identical code. Then Qwen's best three against the router's worst four. Flag the Laguna column as provisional before anyone asks: 200 of its runs died on a server fault and the survivors skew easy.

Next: which questions are hard?

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org09 / 14
§6 · EARLY RESULTS · 6:40

Early results: which kind of SQL question is hardest?

DEEPSEEKQWEN 27BXIYAN 7BLAGUNAROUTER
simple one table.673.827.683.744.685
join across tables.577.543.213.442.446
aggregation counting, grouping.487.486.400.423.405

Execution accuracy, pooled. n = 13–294 per cell, single replicate.

This is the most stable thing I have measured
Five systems, five identical orderings. Four models and a two-model router, and not one of them breaks the pattern.
◆Simple lookups: the model that reads the schema best wins
Qwen leads at .827. These are the questions a biologist could already answer by clicking around — the least valuable ones.
◆Joins: the specialist collapses
.213 for XiYanSQL, against .683 on simple queries. A model trained mostly on single-table benchmarks does not transfer to a 3–4 table join path.
◆Aggregation is a floor, not a model property
All five sit between .400 and .487 — a spread of 0.087, narrower than any other row, and about 30 points below each system's own simple-query score. A bigger model, a second model and a different harness each moved it by less than 0.09.
And this is the awkward part
Counting and grouping is what researchers actually ask for. The system is best at the questions that matter least.
SPEAKER NOTES · 6:40 – 7:25

Point at the red cell, then sweep the whole aggregation row — five systems inside 0.087. The last callout is the one worth landing — strongest where it matters least.

Next: two problems I could not solve.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org10 / 14
§7 · PROBLEM 1 · 7:25

Problem 1: the model runs out of context before it gets to reason

PUT THE WHOLE SCHEMA IN THE PROMPT All 65 tables, every time Context fills up 8k limit reached Never completes 41 of 41 questions RETRIEVE ONLY WHAT IS NEEDED Look up the relevant tables Context stays small Room left to reason Completes all five retrieval agents

The 7B specialist has an 8k context window. Any architecture that pastes the whole schema into the prompt fills that window before the model has written a single line of SQL.

54
Runs that never finished
every one a context overflow
41 / 41
Failure rate of one architecture
the one that injects the full schema
What this does to the benchmark
That 0.159 in the corner of the last table is not the model being bad at SQL. It never got a fair attempt — and a leaderboard would have recorded it as a model failure.
SPEAKER NOTES · 7:25 – 8:05

Left column, then right. The point is that a benchmark number can be about your plumbing. Tie it back to the .159 cell they saw two slides ago.

Next: the harder problem — my own evaluation failed.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org11 / 14
§7 · PROBLEM 2 · 8:05

Problem 2: my evaluation passes answers that are wrong

✓  The SQL is valid
✓  It uses the right schema prefix
✓  It goes through the junction table
✓  It only reads, never writes
✗  The rows are wrong
36
RUNS LIKE THIS

And no run ever got the right rows while breaking a rule — so the checks never fire falsely. They just miss these.

Every rule I wrote encodes something I already knew to look for. These 36 runs broke something I had not thought of yet.

It has happened before, at a bigger scale
An earlier version of my scorer gave 1.0 whenever the expected answer and the model's answer were both empty. A model inventing rows and a model correctly finding nothing scored identically. I only noticed by reading traces.
Which is the uncomfortable part
The evaluation is a system too. It has its own bugs, and nothing else is measuring it.
So what am I
still not measuring?
SPEAKER NOTES · 8:05 – 8:50

Read the four ticks, then the cross, then the number. The empty-set bug is the story — tell it as something I got wrong, not as a lesson. End on the question and stop.

Next: close.

BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.org12 / 14
§8 · CLOSING · 8:50

Benchmark the system
as it grows — not once,
at the end.

What failed? Where did it fail?
Was it the model — or everything around it? As the LLM technologies evolve, the benchmark shall evolve too.
If you build agents
I'd like to hear how you decide yours is working. Hit me up through Linkedin or knock my mail kqueenazima@gmail.com and let's discuss together!.

Thanks to Matin Nuhamunada and the BEAMS Lab, Faculty of Biology, UGM.

SPEAKER NOTES · 8:50 – 9:30

The table is the argument, not a result — both rows are configuration defects, so say "measured my harness" and do not let either number stand as a verdict on the model. If asked: the router had interpret routed to the small tier, which happened to be the SQL specialist; the Laguna losses were 200 connection errors, and its surviving runs were 35% easy questions against a 15% baseline. Neither sweep has been repeated yet.

Then the two questions, slowly. End open; do not tidy it into a conclusion.

Next: one more thing.

kayla queenazima · @kaylaque · chatbgc.matinnu.org13 / 14
APPENDIX 1 · NOT PRESENTED · FOR Q&A

The seven checks that run on every answer.

LAYERCHECKA SCORE LOOKS LIKECOSTWHAT IT CATCHES
1 Does it runEXPLAIN + deny-list1 or 0FREESyntax errors, writes, unknown columns
2 Right rowsgold vs predicted result sets1 or 0FREEWrong joins, wrong filters
3 Right nothingdeclared negative cases only1 or 0FREERows invented for things that don't exist
4 Right methodschema prefix · junction join · SELECT-only0.75 = 3 of 4FREERight rows by luck
5 Answer matches rowsexact numbers + named entities0.60FREECorrect query, invented summary
6 Answer is sensibleLLM judge, rubric + reference0.831 CALLPhrasing the other checks can't score
7 Nothing crashedno pipeline error1 or 0FREETimeouts and rate limits, kept off accuracy
Layer 3 exists because of a bug in my own scorer
Before it, an empty expected answer and an empty prediction both scored 1.0 — so a model that invented rows and a model that correctly found nothing looked identical.
BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.orgA1 / A5
APPENDIX 2 · NOT PRESENTED · FOR Q&A

The whole system, including the parts the talk skips.

INPUT Direct user Typer CLI · chat MCP client any LLM client can call it QUERY HARNESS — FIVE PHASES, 11 SELECTABLE ARCHITECTURES Capturequestion in Retrieveschema + examples Plantables, joins Fetchgenerate + run SQL Interpretanswer from rows CONTROL --arch · 11 architectures t0–t5 · h1/h2 · g1 · t3e --route · model tier pool small / medium / large OUTPUT Answer + SQL + rows back to CLI or MCP client TRAIN MODE (OFFLINE) Schema docs+ past question → SQL Embeddingsnomic-embed-text RETRIEVAL ChromaDBexamples + docs Hybrid searchkeyword + meaning, fused Cross-encoder rerankbge-reranker-base EXECUTION SQL validatorEXPLAIN + deny-list DuckDB — antiSMASH65 tables, read-only CONFIGURES
BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.orgA2 / A5
APPENDIX 3 · NOT PRESENTED · FOR Q&A

The stack, the hardware, and how retrieval works.

ROLEUSED HEREWHY THIS ONE
ServingvLLMContinuous batching, prefix-cache support
Local modelQwen3.6-27B-FP8Official safetensors; FP8 fits the card with context to spare
SQL specialistXiYanSQL 7BCommunity build, AWQ INT4, 8k context
Hosted modelDeepSeek Flash v4Free tier via the opencode endpoint
Fourth modelpoolside/Laguna-XS-2.1-INT4INT4, 8k context; sweep invalid — see A5
Routermodel_router.py per_stageKeyword → tier; Qwen large, XiYanSQL small
OrchestrationLangGraphTyped state, swappable architectures
RetrievalLlamaIndex + ChromaDBKeyword and meaning search, fused by rank
RerankerBAAI/bge-reranker-baseRe-scores the shortlist reading query + doc together
Embeddingsnomic-embed-text-v1.5Runs alongside the 27B on the same card
WarehouseDuckDBSingle file, analytical, no server
Tracing / evalLangfuse · promptfoo + runnerOne span per phase, one per model call
THE HARDWARE

NVIDIA RTX 6000 Ada, 48 GB

Holds the 27B in FP8, a long context window, the embedding model and the reranker at once. No second machine, no network hop.

Two memories, not one
Tool memory holds past question → SQL pairs for few-shot examples. Text memory holds schema docs and term definitions. Different questions need different neighbours.
Why fuse by rank
Keyword and vector scores sit on different scales, so only their ranks can be merged honestly. A cross-encoder then reorders the shortlist.
BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.orgA3 / A5
APPENDIX 4 · NOT PRESENTED · FOR Q&A

What one plain-English sentence actually costs.

gold SQL — difficulty: hard
SELECT r.*, m.*, bgc.*
FROM antismash.regions r
JOIN antismash.modules m ON r.region_id = m.region_id
JOIN antismash.rel_regions_types rt ON r.region_id = rt.region_id
JOIN antismash.bgc_types bgc ON rt.bgc_type_id = bgc.bgc_type_id
WHERE bgc.term ILIKE '%PKS%'
  AND m.trans_at = true;
question: "Which PKS regions have trans-AT modules?"
◆Three joins, none optional
regions and bgc_types have no direct key. Go through the junction table or get nothing.
◆The schema prefix is mandatory
Drop antismash. and the query fails outright — which is the good case.
◆The bad case is quieter
A wrong-but-valid join returns rows. No error, no warning, just a plausible answer — which is what check 4 exists to catch.
BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.orgA4 / A5
APPENDIX 5 · NOT PRESENTED · FOR Q&A

What went wrong, and what is still open.

THINGS THAT DID NOT WORK
◆An earlier campaign measured its own bugs
The schema document had phantom columns and the scorer rewarded empty answers. Every architecture conclusion from it inverted once both were fixed, so none of those numbers appear here.
◆One agent grows its context until it dies
Six Qwen runs lost to timeouts and overflow, all from the same tool-picking loop.
◆One question had to be dropped
Computing length over a 19 GB sequence column runs out of memory on this hardware.
◆Both new sweeps have to be repeated
Laguna lost 200 of 369 runs to server connection errors, leaving a 35%-easy survivor mix against a 15% baseline. The router ran with its tiers inverted — interpret maps to the small tier, which was the SQL specialist — so answer quality landed at the interpreter's level (0.478) rather than the SQL writer's.
◆The router cannot be audited from the traces
One model_name per run, no per-span tier, phases[].details empty. Which model served which call is unrecoverable — so "did not behave like Qwen" is as far as the diagnosis goes.
STILL OPEN
◆A third of correct queries still explain themselves badly
76 of Qwen's 233 correct queries produced an answer that did not match the rows it had just fetched.
◆Two questions may be unfair
They target tables that are empty because of an upstream import gap, not because the answer is no.
◆Everything here is one replicate
Earlier work on this system measured ±0.41–0.46 spread between repeats of the same cell. Per-model totals average that out; per-architecture cells do not.
Raw traces
Every run record — SQL, answer, reasoning, timings, tokens and all seven scores — is public. Please check my numbers.
BENCHMARKING AN LLM INTERFACE · PYCON ID 2026 · chatbgc.matinnu.orgA5 / A5